BrickWright: Can AI Design Structures That Actually Stand?
BrickWright: Can AI Design Structures That Actually Stand? explores a newly reported October 2026 research direction and explains what the underlying study actually says. BrickWright combines an agent-facing brick-assembly interface with a physical-feasibility checker. This original guide examines evidence, applications, limitations, costs and the questions researchers must answer next. It treats a preprint as emerging research rather than a settled breakthrough.
Research status: October 2026 preprint; claims should be checked against the original study and later independent work. Read the primary paper.
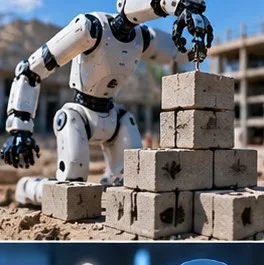
Why this research deserves attention
The most interesting part of brick assembly is not a futuristic headline but a practical scientific question: what can researchers measure, predict, or control that was previously difficult? BrickWright combines an agent-facing brick-assembly interface with a physical-feasibility checker. That proposed mechanism provides a testable starting point. It does not, by itself, prove that the technique is ready for commercial deployment, widespread use, or decisions affecting people.
The October 2026 paper behind this article is a research preprint, which means readers should distinguish its stated results from independent replication and later peer review. The researchers evaluate builds against constraints that distinguish a plausible-looking structure from one a brick system can actually assemble. The point of examining it carefully is to understand the chain of reasoning from an underlying observation to a potentially useful tool. Each link in that chain can be strong or weak, and the weakest link often sets the real-world value.
This guide explores the underlying science, the experimental logic, realistic examples, alternative explanations, failure modes, and questions an independent team would ask. It is intended for curious readers who want more than a headline about brickwright: can ai design structures that actually stand?. Terms are introduced in plain English, while uncertainty is stated explicitly rather than hidden behind confident predictions.
The scientific problem in plain English
Consider the question of structural support in an ordinary research setting. A specialist might have to collect measurements, interpret incomplete signals, and choose what experiment to run next. The difficult part is not simply obtaining a number. It is connecting that number to an underlying process, separating it from noise, and deciding whether the pattern survives when conditions change.
In this context, brick assembly sits within the larger field of generative design, educational tools and embodied planning. Researchers already have established approaches, but each method makes trade-offs among precision, cost, interpretability, speed, and operating conditions. A technique can be excellent at one of these dimensions and still be a poor overall choice. That is why the right comparison is against an honest baseline under matching conditions rather than against a vague claim of what older systems cannot do.
The emerging approach focuses on physical constraints. This matters because apparently small details—sampling rate, device geometry, biological variation, or how an algorithm represents uncertainty—can change the answer. A demonstration becomes more persuasive when the authors explain which assumptions were held fixed and what would happen if those assumptions no longer applied.
How the proposed mechanism works
The central technical idea can be summarized without pretending that every detail is settled: BrickWright combines an agent-facing brick-assembly interface with a physical-feasibility checker. An observer first records or constructs information about checker. The analysis then looks for a structure in those observations that an ordinary measurement or a less targeted model might miss. Finally, a proposed interpretation links the detected structure to the scientific property of interest.
There are three separate questions inside that explanation. First, can the system acquire the necessary signal reproducibly? Second, can the method infer a meaningful property from the signal rather than fit measurement artifacts? Third, does acting on that inferred property improve an external outcome? A paper may answer the first question with strong experiments while leaving the final two open. Keeping them separate prevents a promising method from being mistaken for a finished product.
A helpful analogy is a doctor listening for a subtle rhythm rather than merely checking whether sound exists. The rhythm can contain useful information, but interpretation depends on instrument quality, prior knowledge and competing causes. Likewise, information about physical constraints must be linked to independent observations before researchers can confidently say what it means.
What the new paper actually contributes
The source study describes the following research contribution: The researchers evaluate builds against constraints that distinguish a plausible-looking structure from one a brick system can actually assemble. That is the appropriate center of the story. It is narrower and more defensible than claiming an entire industry has been transformed. The full manuscript is available in the sources section so technically inclined readers can inspect its methods, figures, stated assumptions and limitations for themselves.
A thoughtful reading also asks which results are measurements, which are simulations, and which are extrapolations. Measurements show what happened in a particular setup. Simulations explore how a chosen model behaves. Extrapolations ask what might happen elsewhere. All three can be useful, but they do not carry identical evidential weight. If a simulation agrees with a selected example, additional cases are needed to establish how robust that agreement is.
Published summaries can compress caveats into a sentence or omit them entirely. For that reason, this article avoids interpreting a reported capability as a guarantee of safety, economic benefit or reproducibility. Readers should check the preprint itself for sample size, evaluation design, available code and whether the baseline comparison matches the claimed use case.
A concrete example of possible use
Imagine this scenario: A text prompt asks software to plan a bridge-shaped model that must support its own mass. This is an illustrative application, not a report that the authors have already deployed the approach in that setting. The first step would be a carefully defined question that brick assembly can realistically help answer. The second would be a baseline method and a clearly stated criterion for success. The third would be a blinded or otherwise independent evaluation.
The trial would collect both desirable outcomes and undesirable side effects. It could be tempting to optimize only one headline number, such as accuracy or speed, yet a system that is marginally faster but frequently requires manual correction might not improve real work. For a useful comparison, the same evaluation data, quality controls and resources should be applied to both the new method and the alternative.
If results remained encouraging, the next stage would move beyond familiar examples. Teams would test unexpected inputs, changes in environment and equipment, and people or samples not represented during development. The purpose is to understand what happens when physical constraints behaves differently from the original experiment—not merely to create a polished demonstration.
How scientists would measure success
A good evaluation for this line of work would ask researchers to Measure valid construction rate, structural stability, completion time and transfer to physical bricks. Those measurements are more informative than broad statements about revolutionary capability. They would help readers assess the scientific claim and the costs of applying it. Importantly, the definition of success needs to be agreed upon before inspecting the most favorable results.
Statistical uncertainty matters. A single attractive example may reflect good luck, unusual conditions or selective reporting. Repeated trials, held-out data, independent instruments and confidence intervals reveal how much variability exists. For methods involving learning, a separate dataset from unfamiliar conditions is especially important because performance can fall when the test environment differs from the training environment.
Researchers should also describe negative results. If the technique fails in a particular regime, that boundary can be useful scientific knowledge. It tells engineers where additional measurements or different methods are needed. Transparent reporting of failures makes brick assembly easier to evaluate and less likely to be oversold.
The engineering bottlenecks
One limitation deserves particular attention: The simulator may omit friction, tolerances, damaged pieces or the realities of robotic assembly. This concern is not an argument against exploring the idea. It is a reminder that real systems are networks of interacting constraints. Improving the mathematical or laboratory component might expose a different limiting factor elsewhere in the workflow.
Engineering teams would ask about calibration, maintenance, environmental variation, ease of integration, and how the method behaves at larger scales. Where hardware is involved, manufacturing yield and durability may matter more than a peak laboratory result. Where software is involved, data provenance, computational cost, version changes, and hidden distribution shifts deserve equal attention. Where biological samples are involved, population diversity and measurement consistency cannot be ignored.
Cost must include more than the first purchase or compute bill. There is staff time, validation, quality assurance, downtime, legal review where applicable, and the cost of being wrong. A reliable but slightly less impressive approach can be preferable to an unstable method that requires extensive rescue work.
What existing methods still do well
New techniques should be understood alongside conventional options. Standard instrumentation, carefully designed physical models, established statistical tools, and expert judgment often remain competitive because they are familiar and their limitations are documented. For brick assembly, a fair test would compare the proposed method with the strongest practical alternative, not just the simplest straw-man baseline.
A hybrid approach may ultimately prove more effective. Researchers could use a conventional measurement to anchor the result, apply the newer method to capture an additional signal, and have a human expert review cases that fall outside validated conditions. This architecture can preserve some of the benefits of innovation while reducing dependence on one fragile component.
The value of physical constraints should therefore be framed as an empirical question: does it add information or capability that changes a decision? If it merely produces a more elaborate representation of facts already available through cheaper methods, its long-term role may be limited. If it consistently exposes otherwise invisible structure, its importance could be substantial.

What independent replication should look like
Independent replication would start with a readable protocol and clear access to whatever data, code, configurations or materials can legally and safely be shared. Another group should know exactly what outcome to reproduce. If the study relies on a particular assumption about checker, the assumption needs to be documented so that failure to reproduce does not become an argument over hidden setup details.
The replication team should repeat at least one core result, then vary a meaningful condition. Testing only the original circumstances checks whether the instructions are reproducible; testing a variation checks whether the underlying idea generalizes. Both are valuable. Ideally, the team would report unexpected failures and disagreements rather than tuning conditions until they resemble the first paper.
For readers, replication is not a box that can be checked from a news announcement. It is a gradual process involving independent groups, new instruments or settings, and converging evidence. A single October 2026 preprint is therefore a reason to investigate brick assembly, not a reason to treat every suggested application as established.
Safety, privacy and social consequences
Possible benefits of brick assembly have to be weighed against the setting in which it might be used. In research, a false result can waste time and resources; in a deployed system, the same kind of error could influence material selection, operational safety, access decisions, medical interpretation or environmental assessments. Risk should be defined in terms of realistic users and consequences rather than abstract enthusiasm or fear.
When datasets or automated recommendations are involved, provenance and accountability are important. People should be able to learn what information was used, what the system is not qualified to infer, and who can correct a mistake. When equipment is involved, physical safeguards and conservative operating limits are appropriate. When scientific communication is involved, separating confirmed results from hypotheses prevents the public from making decisions on a misleading impression of certainty.
An ethical development process also asks who bears the costs of experimentation and who gains access to its benefits. These questions do not invalidate research. They help determine whether an innovation produces durable public value rather than only an impressive technical demonstration.
What to watch in the next research cycle
The most informative follow-up would directly address the uncertainty surrounding physical constraints. Researchers could test on unfamiliar data, share independent measurements or publish a careful comparison with alternative methods. More varied evidence would make it possible to separate the distinctive contribution of the proposed mechanism from circumstances that happened to favor the initial result.
Look for papers that openly report boundaries as well as successes. A replicated effect that works only within a narrow regime is still scientifically important, particularly if its physical explanation is clear. A spectacular one-off result with no meaningful controls may be less useful than a modest improvement demonstrated repeatedly under transparent conditions.
The long-term promise of brick assembly lies in strengthening the bridge between explanation and reliable action. The October 2026 work offers a research direction; its eventual significance will depend on independent experiments, critical debate and disciplined engineering.
How to read the original research critically
Begin with the abstract, but do not stop there. Identify the main claim, then find the figure or experiment that most directly supports it. Next, read the methods describing how checker was obtained or represented. Ask whether the sampling procedure, controls and definitions could create an attractive result without demonstrating the proposed mechanism.
Then examine the comparison. Does the new approach improve on a well-tuned relevant baseline, or on a deliberately simple alternative? Are gains consistent across conditions, or concentrated in a few favorable cases? Where the work includes simulations, what experimental evidence supports the model assumptions? Where learning is involved, is there leakage from training examples into evaluation?
Finally, read the limitations with the same care as the conclusion. The authors may be explicit about unresolved issues. The right outcome of a first reading is not necessarily belief or disbelief; it is a short list of specific claims that can be checked in later work.
The main takeaways
The core reason this topic matters is precise: BrickWright combines an agent-facing brick-assembly interface with a physical-feasibility checker. The source study adds a particular piece of evidence: The researchers evaluate builds against constraints that distinguish a plausible-looking structure from one a brick system can actually assemble. Together, those statements establish a meaningful research story, but they do not eliminate the need for independent evaluation.
The strongest near-term application would be a controlled study in generative design, educational tools and embodied planning where researchers can directly measure physical constraints. Success should be assessed using realistic tests, explicit costs and documented failure modes. The key obstacle remains that the simulator may omit friction, tolerances, damaged pieces or the realities of robotic assembly.
The final lesson is a general one for emerging technology: separate what a method demonstrates today from what engineers hope it might enable tomorrow. That distinction does not diminish the achievement. It makes the result more useful to scientists, policymakers and curious readers who want to understand progress without exaggeration.
Frequently asked questions
Is this research already proven?
Not in the broad sense. The October 2026 manuscript is a research preprint with a defined claim, not proof that brick assembly works reliably in every real-world setting. Independent replication matters.
What is the central idea?
BrickWright combines an agent-facing brick-assembly interface with a physical-feasibility checker.
What evidence is currently available?
The researchers evaluate builds against constraints that distinguish a plausible-looking structure from one a brick system can actually assemble. The original manuscript is linked below so readers can inspect the reported methods and results.
What is the most realistic application?
An early application is likely to be a controlled study in generative design, educational tools and embodied planning. A text prompt asks software to plan a bridge-shaped model that must support its own mass. This is an example, not an announcement of an operating product.
What could go wrong?
The simulator may omit friction, tolerances, damaged pieces or the realities of robotic assembly. Practical tests need to examine these circumstances rather than assume ideal conditions.
How would researchers judge whether it works?
Measure valid construction rate, structural stability, completion time and transfer to physical bricks. The design should include a baseline, independent observations and transparent uncertainty reporting.
Is the work peer reviewed?
The linked source is an arXiv preprint. Readers should check its current status before describing it as journal peer reviewed.
What should a beginner read first?
Start with the original abstract, identify the main measurement about checker, and then read the methodology and limitations before focusing on future applications.
Where can I follow updates?
Follow the arXiv record, linked below, for revised versions and related papers. Also monitor independent studies addressing physical constraints and testing unfamiliar settings.
Sources and further reading
- Original October 2026 research preprint (arXiv:2610.31651).
- Disruptive Concepts, week of October 26, 2026: research roundup (secondary editorial context).
- arXiv Help: understanding the research repository and preprints.
Editorial note: This article provides educational interpretation, not medical, investment, operational-safety or engineering certification advice. Illustrative scenarios are labeled as such.
The conversation
Post a Comment