Polymer-brush research combines simulation, experimentation and machine learning to design functional surfaces. This explainer separates the scientific principle from the claims that still need testing.

The central question
Interfacial Intelligence raises a deceptively simple question: which part of a complicated scientific system can investigators change, and how will they know that the result came from that change rather than from an uncontrolled variable? In a laboratory, answering that question demands much more than an attractive demonstration. It requires a baseline, a specific intervention, a record of what was measured, and a clear description of uncertainty.
The October 2026 research angle here is specific: Polymer-brush research combines simulation, experimentation and machine learning to design functional surfaces. The useful way to read it is as an account of an experimental direction, not as a guarantee that a product or clinical technique has arrived. A finding can be important because it makes a previously difficult measurement possible, even when the next decade of applications is still uncertain.
What researchers are trying to change
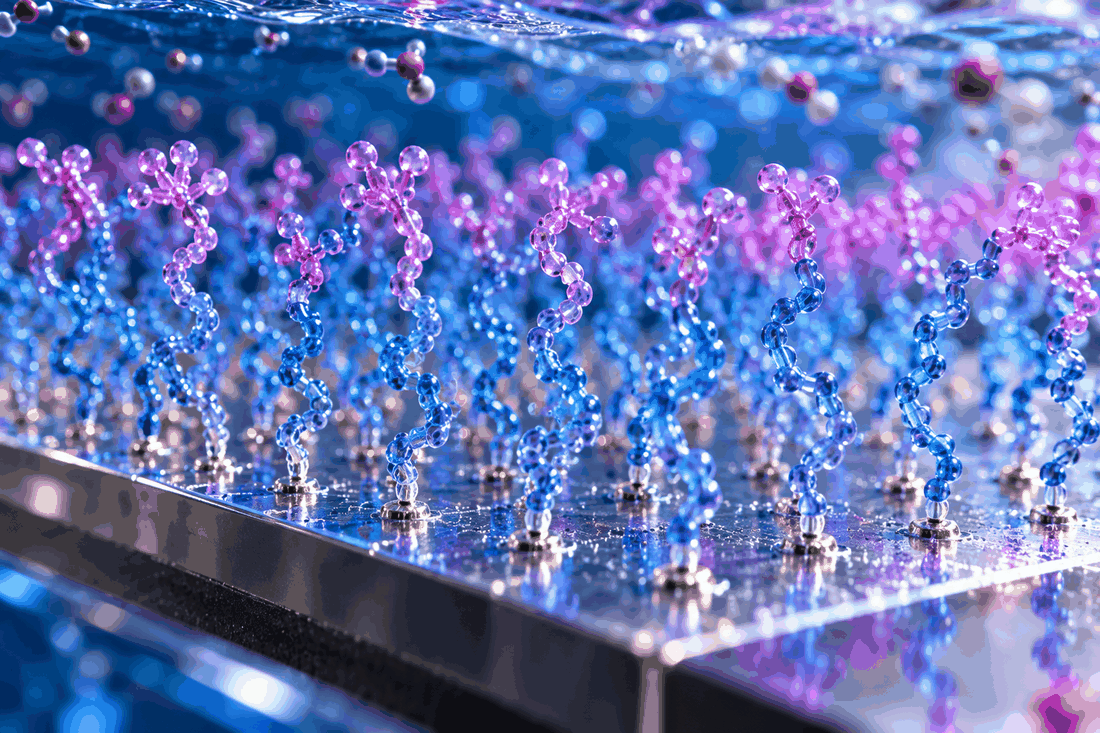
The research objective can be stated without hype: A polymer brush is a layer of molecular chains tethered to a surface. Density, length and solvent environment determine how the interface behaves. Scientists then need to convert that principle into a working procedure that can be repeated by another laboratory with different instruments, materials or operators.
Interfacial Intelligence should be read in layers: what researchers designed, what they directly observed, and what future application people may imagine. Article 4 treats those as separate claims, especially because polymer-brush research combines simulation, experimentation and machine learning to design functional surfaces.
How the mechanism works
A polymer brush is a layer of molecular chains tethered to a surface. Density, length and solvent environment determine how the interface behaves. To connect this concept to an experiment, identify the input, the relevant physical or chemical interaction and the output that the instruments record. A claim becomes testable only when those components are defined.
The main confounders in Interfacial Intelligence may include environmental drift, sample differences, processing assumptions, or the choice of comparator. Article 4 returns to controls because those alternatives can mimic a genuine effect.
A practical thought experiment
Consider this example: Consider an antifouling membrane where slight variations in chain spacing change the rate at which proteins adsorb. This is an explanatory scenario, not a description of an additional reported experiment. It makes the trade-offs visible by connecting the mechanism to an imaginable setting.
Experimental design choices shape the story of Interfacial Intelligence. A setup optimized for sensitivity, speed, or visual impact may sacrifice durability or realism. Article 4 therefore pays attention to trade-offs, not just peak performance.
What the evidence does and does not show
The available source describes the topic this way: Polymer-brush research combines simulation, experimentation and machine learning to design functional surfaces. Readers should distinguish an observation in the reported experimental setting from a result demonstrated across many settings.
For Interfacial Intelligence, a measured signal is not automatically a complete explanation. Competing mechanisms may fit the same observation, so article 4 emphasizes tests that discriminate among interpretations rather than relying on a striking image alone.
Engineering and measurement challenges
The next round of engineering questions is concrete: A model trained on ideal simulations must be checked on contaminated, manufactured and aging real surfaces. These are the kinds of details that turn a one-off demonstration into a dependable scientific or industrial system.
Uncertainty in Interfacial Intelligence can come from hardware drift, material variability, environmental noise, or analysis choices. Article 4 treats those sources of error as part of the story because the interpretation depends on them.
What would meaningful progress look like?
Meaningful progress would include a replicable performance benchmark, documented uncertainty and a comparison with a realistic alternative. For interfacial intelligence, the strongest follow-up would test whether the reported mechanism persists outside the narrow conditions in which it was first observed.
Interfacial Intelligence is not automatically deployment-ready. Practical use would require durability, independent benchmarks, and testing under conditions closer to the intended environment. For now, article 4 describes a research capability, not a finished product.
Questions readers should ask
A careful reader of Interfacial Intelligence should ask what was measured, how it was calibrated, what controls were used, and how many trials were reported. Those details determine how strongly article 4 supports its central claim.
Claims about Interfacial Intelligence also depend on the source. A news summary can explain the idea, but the technical paper or mission documentation should carry the evidentiary weight. That distinction matters throughout article 4.
Frequently asked questions
Is Interfacial Intelligence already an everyday technology? No. Article 4 describes an active research direction or mission-level capability whose broader availability still depends on engineering, verification, and, where relevant, approval.
The most promising aspect of Interfacial Intelligence is foundational rather than final: it may give researchers a better handle on a difficult phenomenon. That is why article 4 frames the advance as enabling future work, not guaranteeing a product.
What could prevent practical use? A model trained on ideal simulations must be checked on contaminated, manufactured and aging real surfaces.
To follow Interfacial Intelligence well, start from the cited source trail, then look for a primary paper, mission report, or technical update. Article 4 is strongest when later coverage confirms its methods and boundaries.
Sources and further reading
Research and background source for article 4: https://phys.org/news/2026-10-interfacial-intelligence-polymer.html . This is the manifest starting point for Interfacial Intelligence; readers should treat it as a gateway to deeper verification rather than the final word on the subject.
Editorial note for article 4: this feature explains Interfacial Intelligence and avoids asserting any unverified clinical result, consumer release date, or unsupported numerical performance claim.
From concept to a repeatable experiment
For interfacial intelligence, the experimental pipeline starts with a controllable input: tethered polymer-chain architecture. Researchers must define the input in quantities that another laboratory could reproduce rather than relying on labels such as “strong,” “gentle,” or “high resolution.” Depending on the apparatus, those quantities may include duration, intensity, sample geometry, concentration, timing and temperature. Even where a news article omits technical specifications, these are the variables a primary methods section should explain. The purpose is not bureaucratic precision; it is to distinguish an actual physical mechanism from an accidental change in operating conditions.
The proposed pathway is molecular packing and surface interactions. To test whether the pathway operates as imagined, a study needs more than a before-and-after photograph. One control should receive the same preparation without the intended stimulus. Another, where practical, should use a version of the material or instrument that lacks the crucial active feature. If the output persists in both controls, researchers need to revisit the explanation. If it appears only when the necessary components are present, the evidence becomes stronger, though not necessarily conclusive.
What is the output? For this topic a natural family of readouts is wetting and fouling resistance. A team should predefine the primary endpoint and explain whether other measurements are supporting indicators. As an example, a change in a signal can be meaningful even when the device produces no useful product. Conversely, a device may appear successful on a practical endpoint yet leave its underlying mechanism uncertain. Both cases deserve precise reporting. The best research designs measure function and mechanism separately and explain where they agree.
Reproducibility for Interfacial Intelligence means another team should be able to repeat the workflow with comparable results. If outside groups struggle, that may reveal hidden sensitivities rather than simple failure. Article 4 should be read with that follow-up question in mind.
A worked comparison of the alternatives
A useful comparison for interfacial intelligence is trial-and-error surface formulation. That does not mean the older approach is obsolete. It means the new approach should be assessed against what established methods already do well. Researchers can make a three-column comparison: the advantage the new mechanism promises, the cost paid for that advantage and the conditions in which the older method remains preferable. Such a table can prevent a laboratory improvement from being mistaken for a universal advance.
Suppose a conventional method produces a moderate result with reliable equipment and well understood maintenance, while tethered polymer-chain architecture achieves a stronger result only under tightly controlled laboratory conditions. Is the new method better? For fundamental science, the answer might be yes because a new mechanism has been observed. For manufacturing, the answer might be no until failure rates, materials costs and quality control improve. Two honest assessments can therefore reach different judgments without either being wrong.
Another comparison concerns time scale. A one-minute test can reveal a transient effect yet tell us little about a process that must operate for months. For membranes and medical devices, duration and environmental exposure would be central questions. Testing how molecular packing and surface interactions behaves when temperature, workload or sample composition shifts gives a better picture of performance than maximizing a single headline figure. The goal is to evaluate the operating envelope, not to reproduce the most favorable trial.
Comparisons for Interfacial Intelligence are only meaningful when both methods face similar constraints. If one approach is tested under easier conditions, the headline comparison can mislead. Article 4 therefore treats context as part of the evidence.
How to interpret measurements responsibly
Numbers do not interpret themselves. When the reported output is wetting and fouling resistance, a reader should ask for units, calibration and the uncertainty attached to each observation. An estimated change is not the same as a directly observed one, and the difference matters particularly when calculations or algorithms reconstruct signals from raw detector output. Good figures show representative measurements while also revealing spread across repeated samples.
The major confounders for this case include synthesis variance and simulation-to-real gaps. Each has a distinct diagnostic strategy. Drift can be monitored using a reference sample; contamination can be checked through blanks or chemical analysis; algorithmic bias can be tested with held-out data. A study need not eliminate every conceivable uncertainty, but it should explain which uncertainties were tested and how much they could alter the conclusion. If the largest uncertainty is comparable to the effect, a confident headline may be premature.
A stronger reading of Interfacial Intelligence comes from distributions rather than single best runs. Variation, outliers, and exclusions matter because repeatability across many trials is more persuasive than one impressive example in article 4.
External validity is the final measurement issue. A controlled demonstration can be exactly correct and still fail to predict field performance. The relevant validation tools might include contact angles, force curves and adsorption tests. Each test answers a particular question; none alone proves all claimed applications. Readers can look for convergence across independent forms of evidence, especially when a claim is likely to influence medical, environmental or infrastructure decisions.
What a real-world pilot would require
Imagine that a research group wants to move from a carefully supervised demonstration of tethered polymer-chain architecture to a limited trial connected with membranes and medical devices. The first task would be to specify what success means in that setting. It might be a minimum useful operating duration, a clearly defined error rate, acceptable maintenance cost or performance under an expected range of real-world conditions. Without those thresholds, teams may keep redefining success around whichever result looks best.
An early pilot should include a failure-recovery plan. If molecular packing and surface interactions stops working, can the experiment safely return to its baseline state? Can an operator recognize trouble from a readily available measurement, or does diagnosis require specialized equipment? In medicine, safety and biocompatibility may dominate the decision. In aerospace, fault tolerance and communication windows may matter more. In materials processing, contamination and energy use may be the limiting factors. These differences shape the correct validation route.
For Interfacial Intelligence, the cost story matters too: specialized equipment, staff time, and sample preparation may determine whether this result stays a laboratory demonstration or matures into a usable method. That practical question sits behind article 4.
Independent replication is especially important for Interfacial Intelligence because the inventing team may rely on tacit know-how. If other groups reproduce the effect, confidence rises sharply; if not, article 4 becomes a prompt for closer methodological scrutiny.
The next questions scientists can answer
The first unanswered question is causal: which element of molecular packing and surface interactions is indispensable, and which supporting elements could be changed without losing the effect? Answering it would help distinguish a general scientific principle from a recipe that works only in one experimental arrangement. Teams can vary one factor at a time for clarity, then test interactions among factors when those interactions are likely to matter.
The second is quantitative: what limits wetting and fouling resistance? A useful research program should seek the point where performance stops improving and identify what causes the plateau. Perhaps the limit comes from fundamental physics, perhaps from impurities, and perhaps from a measurement device that is no longer sensitive enough. Those explanations lead to very different investments. Identifying the bottleneck is often more valuable than making another incremental gain under the same conditions.
The third is long-term behavior. For membranes and medical devices, repeat use, manufacturing differences and contact with the surrounding environment can change a system that behaves perfectly in the first demonstration. Investigators can accelerate some aging tests, but they should not assume that accelerated stress always reproduces real-world degradation. Longitudinal observation remains important whenever a claimed application depends on reliability.
The fourth is comparison with alternatives. A promising experiment should eventually be evaluated against trial-and-error surface formulation, with transparent constraints and meaningful endpoints. The strongest future news story would not simply announce that interfacial intelligence “works.” It would show exactly where it outperforms available methods, where it does not, and what the remaining trade-offs mean.
The durable takeaway from Interfacial Intelligence is improved scientific literacy, not a guaranteed product timeline. Article 4 matters because it helps readers distinguish a foundational demonstration from later application claims.
The conversation
Post a Comment